One of the most expensive mistakes startups make when adopting artificial intelligence is assuming they need to "train their own model." Founders spend months collecting training datasets, renting cloud GPUs, and training custom LoRA adapters to teach an LLM company policies. Six months later, the model's knowledge is obsolete, the weights cannot cite their sources, and the project is abandoned. Below is why fine-tuning is rarely the right starting architecture and the three cheaper alternatives you must exhaust first.
The golden rule of modern AI engineering is simple: knowledge problems are context problems. If your model fails because it does not know your product pricing, return policy, or internal client notes, fine-tuning is the wrong solution.
Of behavioral issues solved by proper few-shot prompt schemas.
Model weights cannot dynamically update when company pricing changes.
GPU compute saved by LoRA adapters over full parameter tuning.
Architectural layers to implement before training custom weights.
1. The fine-tuning trap: Baking dynamic facts into static weights
When an AI model hallucinates your product refund window, non-technical managers often declare: "We need to fine-tune the model on our handbook."
Fine-tuning modifies the mathematical weights inside the neural network. While this is effective for teaching a model a rigid grammatical syntax or brand voice, it is terrible for storing factual data:
- Instant Obsolescence: The moment you update your service prices next week, your fine-tuned model continues quoting last week's numbers. Updating the weights requires re-training and re-evaluating the entire dataset.
- No Source Traceability: Fine-tuned weights cannot provide exact document citations or URL links. The model simply bakes facts into probabilistic guesses.
- High Maintenance Overhead: Maintaining custom weights locks you into a specific model generation. When OpenAI or Anthropic releases a smarter base model next quarter, your custom adapter must be retrained from scratch.
Source: Winder.ai: LLM Architecture Framework: Fine-Tuning vs RAG vs Prompting
2. Comparing the three architectural approaches
Before spending engineering budget on cloud GPUs, evaluate where your requirements sit across the capability matrix:
Swipe through the numbers
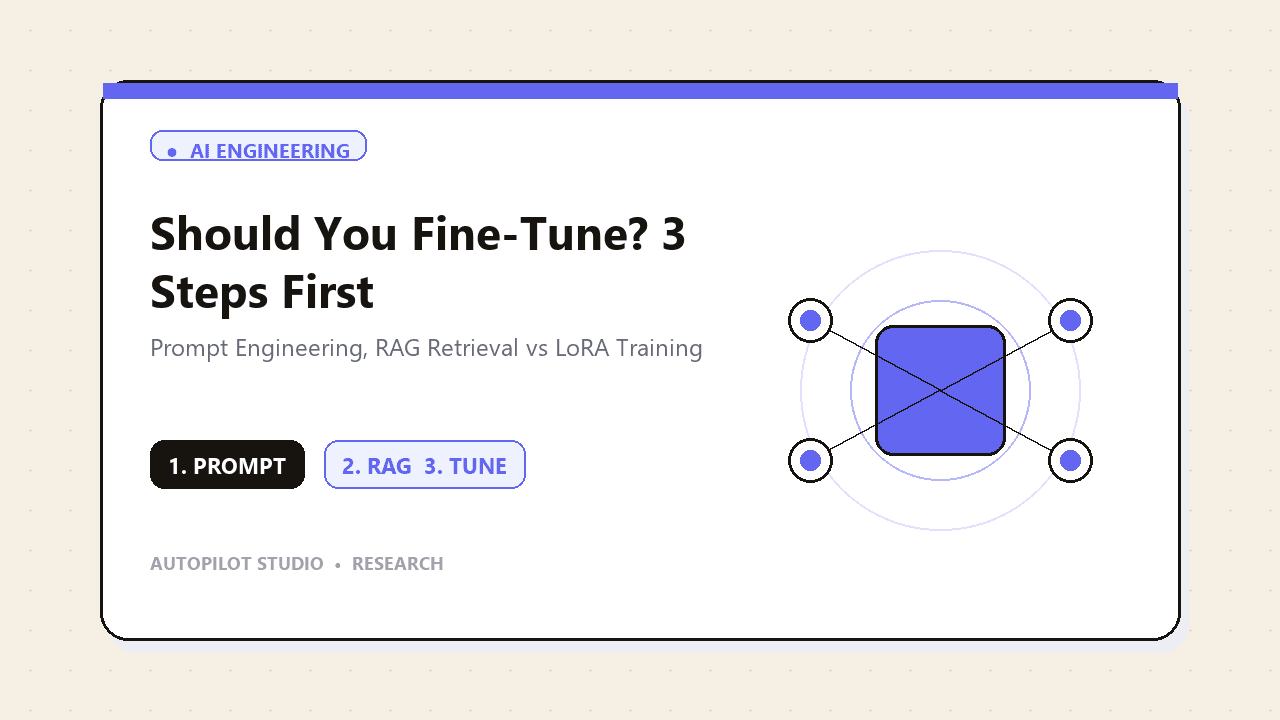
- Prompt EngineeringInput Contextfastest, cheapest, zero training cost; uses base model
- Vector RAGDynamic Datafetches fresh company docs at query time; easy source links
- Fine-Tuning (LoRA)Model Weightschanges how the model talks; expensive maintenance
3. The 3 alternatives to deploy before fine-tuning
Follow this progressive optimization ladder. Only move to the next tier when the previous layer hits a verified capability wall:
- 01
Layer 1: Structured few-shot prompt engineering
Use OpenAI or Anthropic structured JSON schema outputs. Provide 3 to 5 clear input-output examples directly in the system prompt to enforce output formats.
- 02
Layer 2: Retrieval-Augmented Generation (RAG)
Store your company documentation in a vector database like Pinecone or pgvector. Dynamically inject the most relevant paragraphs into the prompt at runtime.
- 03
Layer 3: Prompt caching and context compression
Leverage provider prompt-caching discounts ($0.10/M tokens) to pass comprehensive guidelines without multiplying execution costs.
4. Dynamic facts vs Fixed behavior: The critical divide
Drag the slider below to contrast when to use Retrieval-Augmented Generation versus when to deploy Low-Rank Adaptation (LoRA):
RAG is for what the model knows (fresh inventory, pricing, client names). Fine-tuning is for how the model behaves (tone, specialized dialect, or rigid proprietary JSON formats).
5. The only 3 scenarios where fine-tuning makes sense
You should only consider training LoRA adapters if you meet one of these three specific criteria:
- Extreme prompt compression at scale: Your system prompt requires 80 heavy few-shot examples that drive up token costs across millions of monthly calls. Fine-tuning bakes those examples into weights, slashing prompt token fees.
- Proprietary syntax enforcement: You need a model to output deeply nested, proprietary domain notation (such as medical records or custom CAD DSLs) where prompt formatting fails 5% of the time.
- Small model distillation: You want to train an open-source 8B model (like Llama 3) to mimic the performance of a 70B model on a single narrow classification task to run cheaply on local hardware.
If your problem is simply that the model doesn't know your business data, build a clean RAG pipeline.
If your agency or enterprise needs guidance choosing between RAG and custom fine-tuning, our team designs production architectures that scale cost-effectively.